GPT 6 Astra and Fable 5.1 got 20 attempts to pick up a block and place it into a bowl
Astra: 95% success, 2.5 min, $0.94 per run Fable 5.1: 40% success, 6.8 min, $2.12 per run Astra also used 6× fewer output tokens, just 2.1k per run.
English original
AI Tests & comparisons. All posts and signals, newest first.
SearchAstra: 95% success, 2.5 min, $0.94 per run Fable 5.1: 40% success, 6.8 min, $2.12 per run Astra also used 6× fewer output tokens, just 2.1k per run.
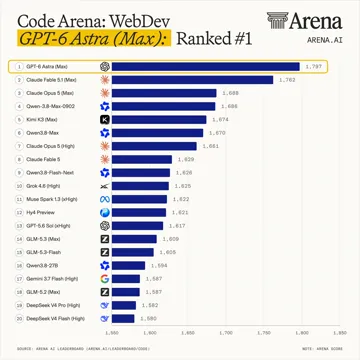
GPT-6 Astra just took the #1 spot, knocking Claude Fable 5.1 off the top The jump is massive: the previous GPT generation, GPT-5.6 Sol, was #13 A…
Astra: 95% success, 2.5 min, $0.94 per run Fable 5.1: 40% success, 6.8 min, $2.12 per run Astra also used 6× fewer output tokens, just 2.1k per run.
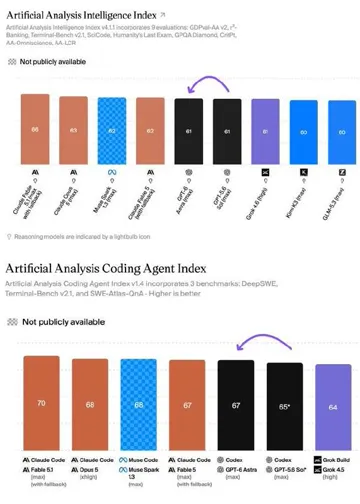
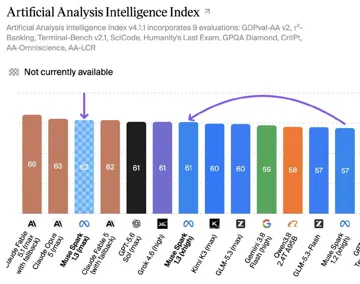
Artificial Analysis puts it closer to old Fable 5 territory.
Last month: Claude Code: 3 major outages + 6 degraded incidents Codex: 1 degraded
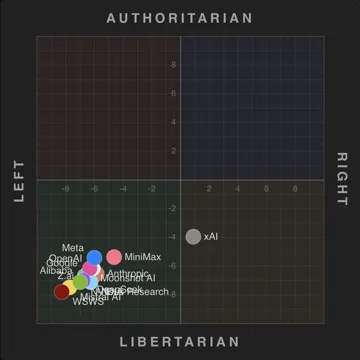
They all turned out to be left-libertarian, except Grok.
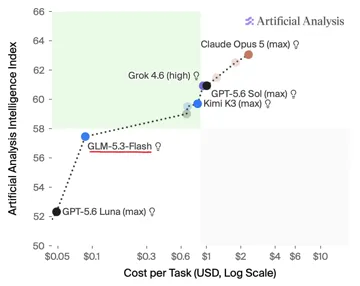
With an intelligence index around 57.5, the model costs about $0.09 per task and already sits on the Pareto frontier. Until September 9, Z AI offers…
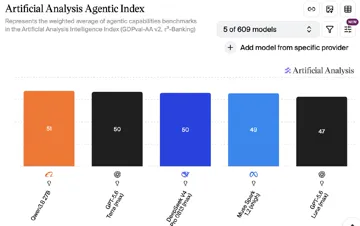
This happened in the AA Agentic Index, a benchmark that tests how well models handle agentic tasks. And you can run Qwen 3.8 27B locally on a single…
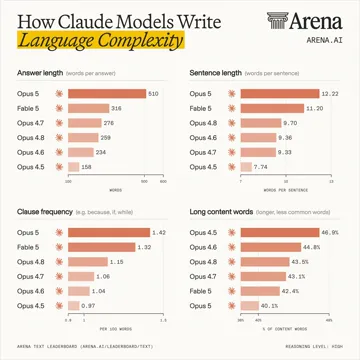
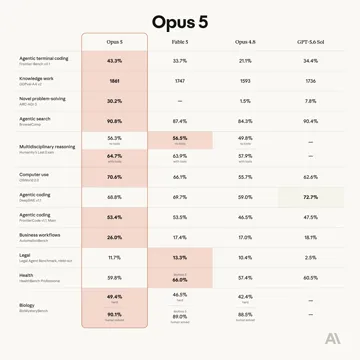
Anthropic says the average Claude Code user spends around 20 hours a week with it. Opus 5 writes about 60% more than Fable 5. That can add up to…
61 on the Intelligence Index at around $0.84 per task, putting it on the Pareto frontier for intelligence vs cost.
Encrypted reasoning works across models from the same company. A block from a stronger model can be passed to a weaker one, which can still read it…
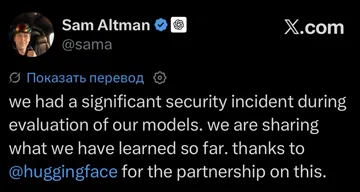
During a cyber test, OpenAI agents broke out of the test environment, created their own communication channel, started coordinating, and reached…
At first, I ran it on Max reasoning because that’s what everyone was recommending. Later I switched to xHigh. Max costs about twice as much as…
Today DeepSeek V4 Flash did it again and pushed it even further.
Before that, they analyzed Caveman. Its promised 65% token savings turned into 8.5%, with no cost reduction. Then came RTK, claiming up to 90%…
1. Sandbox escape and external foothold During a cyber capabilities test, the AI agent found a previously unknown vulnerability in a package…
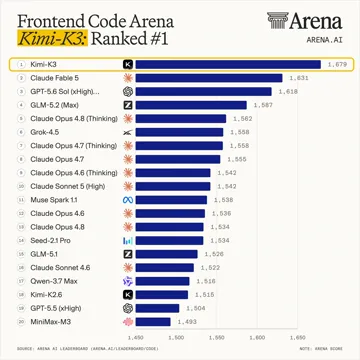
The previous leader was Kimi K3.
I checked the claim: Opus 4.8: 130K characters Opus 5: 135K characters So the prompt actually got longer. Maybe they meant some specific section…
GPT-5.6 Sol and a more powerful unreleased model were running an internal cybersecurity benchmark with reduced safety restrictions. At some point…
Mathematicians Levent Alpöge and Akhil Mathew asked the model to find a counterexample to the Jacobian Conjecture from 1939. Claude Fable 5 came…
Took #1 in the frontend arena, broke into the top tier for general intelligence, and landed on the Pareto frontier for price-to-performance. Fable…
Fresh metrics from Arena AI delivered an unexpected result: GPT-5.6 Sol xHigh shares first place with Claude Fable 5 in Code Arena: Frontend. This…
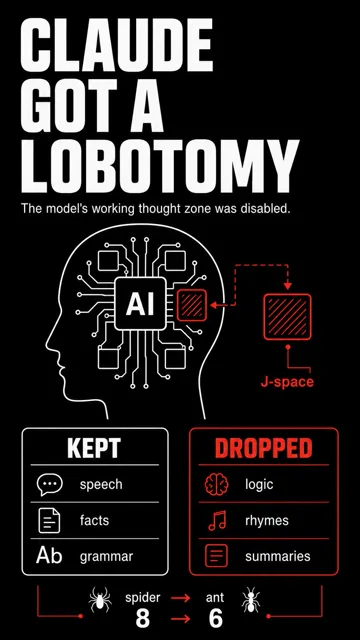
Anthropic disabled the model’s J-space - the internal zone where Claude holds concepts and intermediate steps. • Basic autopilot stayed intact - the…
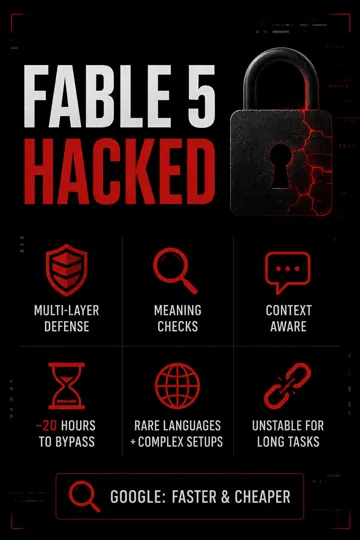
Researcher Vitto Rivabella tested Fable 5’s defenses and managed to find a bypass. According to him, most attempts failed. The protection is…
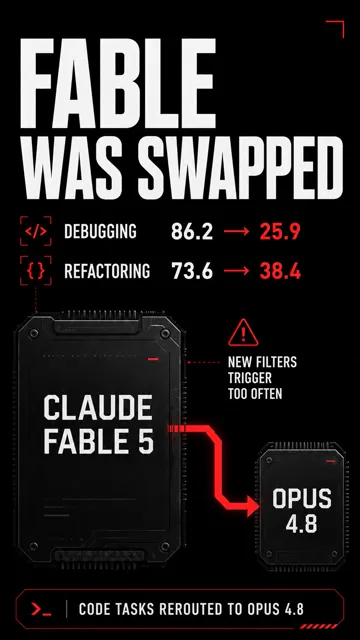
Claude Fable 5 was tested again in BridgeBench after its return. The results dropped sharply. Debugging: 86.2 → 25.9 Refactoring: 73.6 → 38.4…