Alex Getmanearly AI signals
Alex Getman @alexgetmancom · · Updated

Releases

Claude Opus 5 is out

⚡️ Claude Opus 5 is out

Anthropic has released a new model built for coding and complex work. Opus 5 checks its work more carefully and doesn’t give up after the first failed attempt. When the obvious approach doesn’t work, it finds another way. In one benchmark, it even built its own computer vision pipeline to reconstruct a 3D model from an image.

In terms of performance, Opus 5 comes close to Fable 5, while tasks cost roughly half as much. In some evaluations, it also beats Fable on price-to-performance.

API pricing reminder: $5 per 1M input tokens and $25 per 1M output tokens.

Table comparing the performance of models Opus 5, Fable 5, Opus 4.8, and GPT-5.6 Sol across various benchmarks including coding, search, and problem-solving. Opus 5 shows high scores in most categories.
Graph titled "Agentic coding by effort level" showing how the scores of models Opus 5, Fable 5, Opus 4.8, and GPT-5.6 Sol increase with the cost per attempt (USD, log scale). Opus 5 demonstrates the best performance at medium and high cost levels.
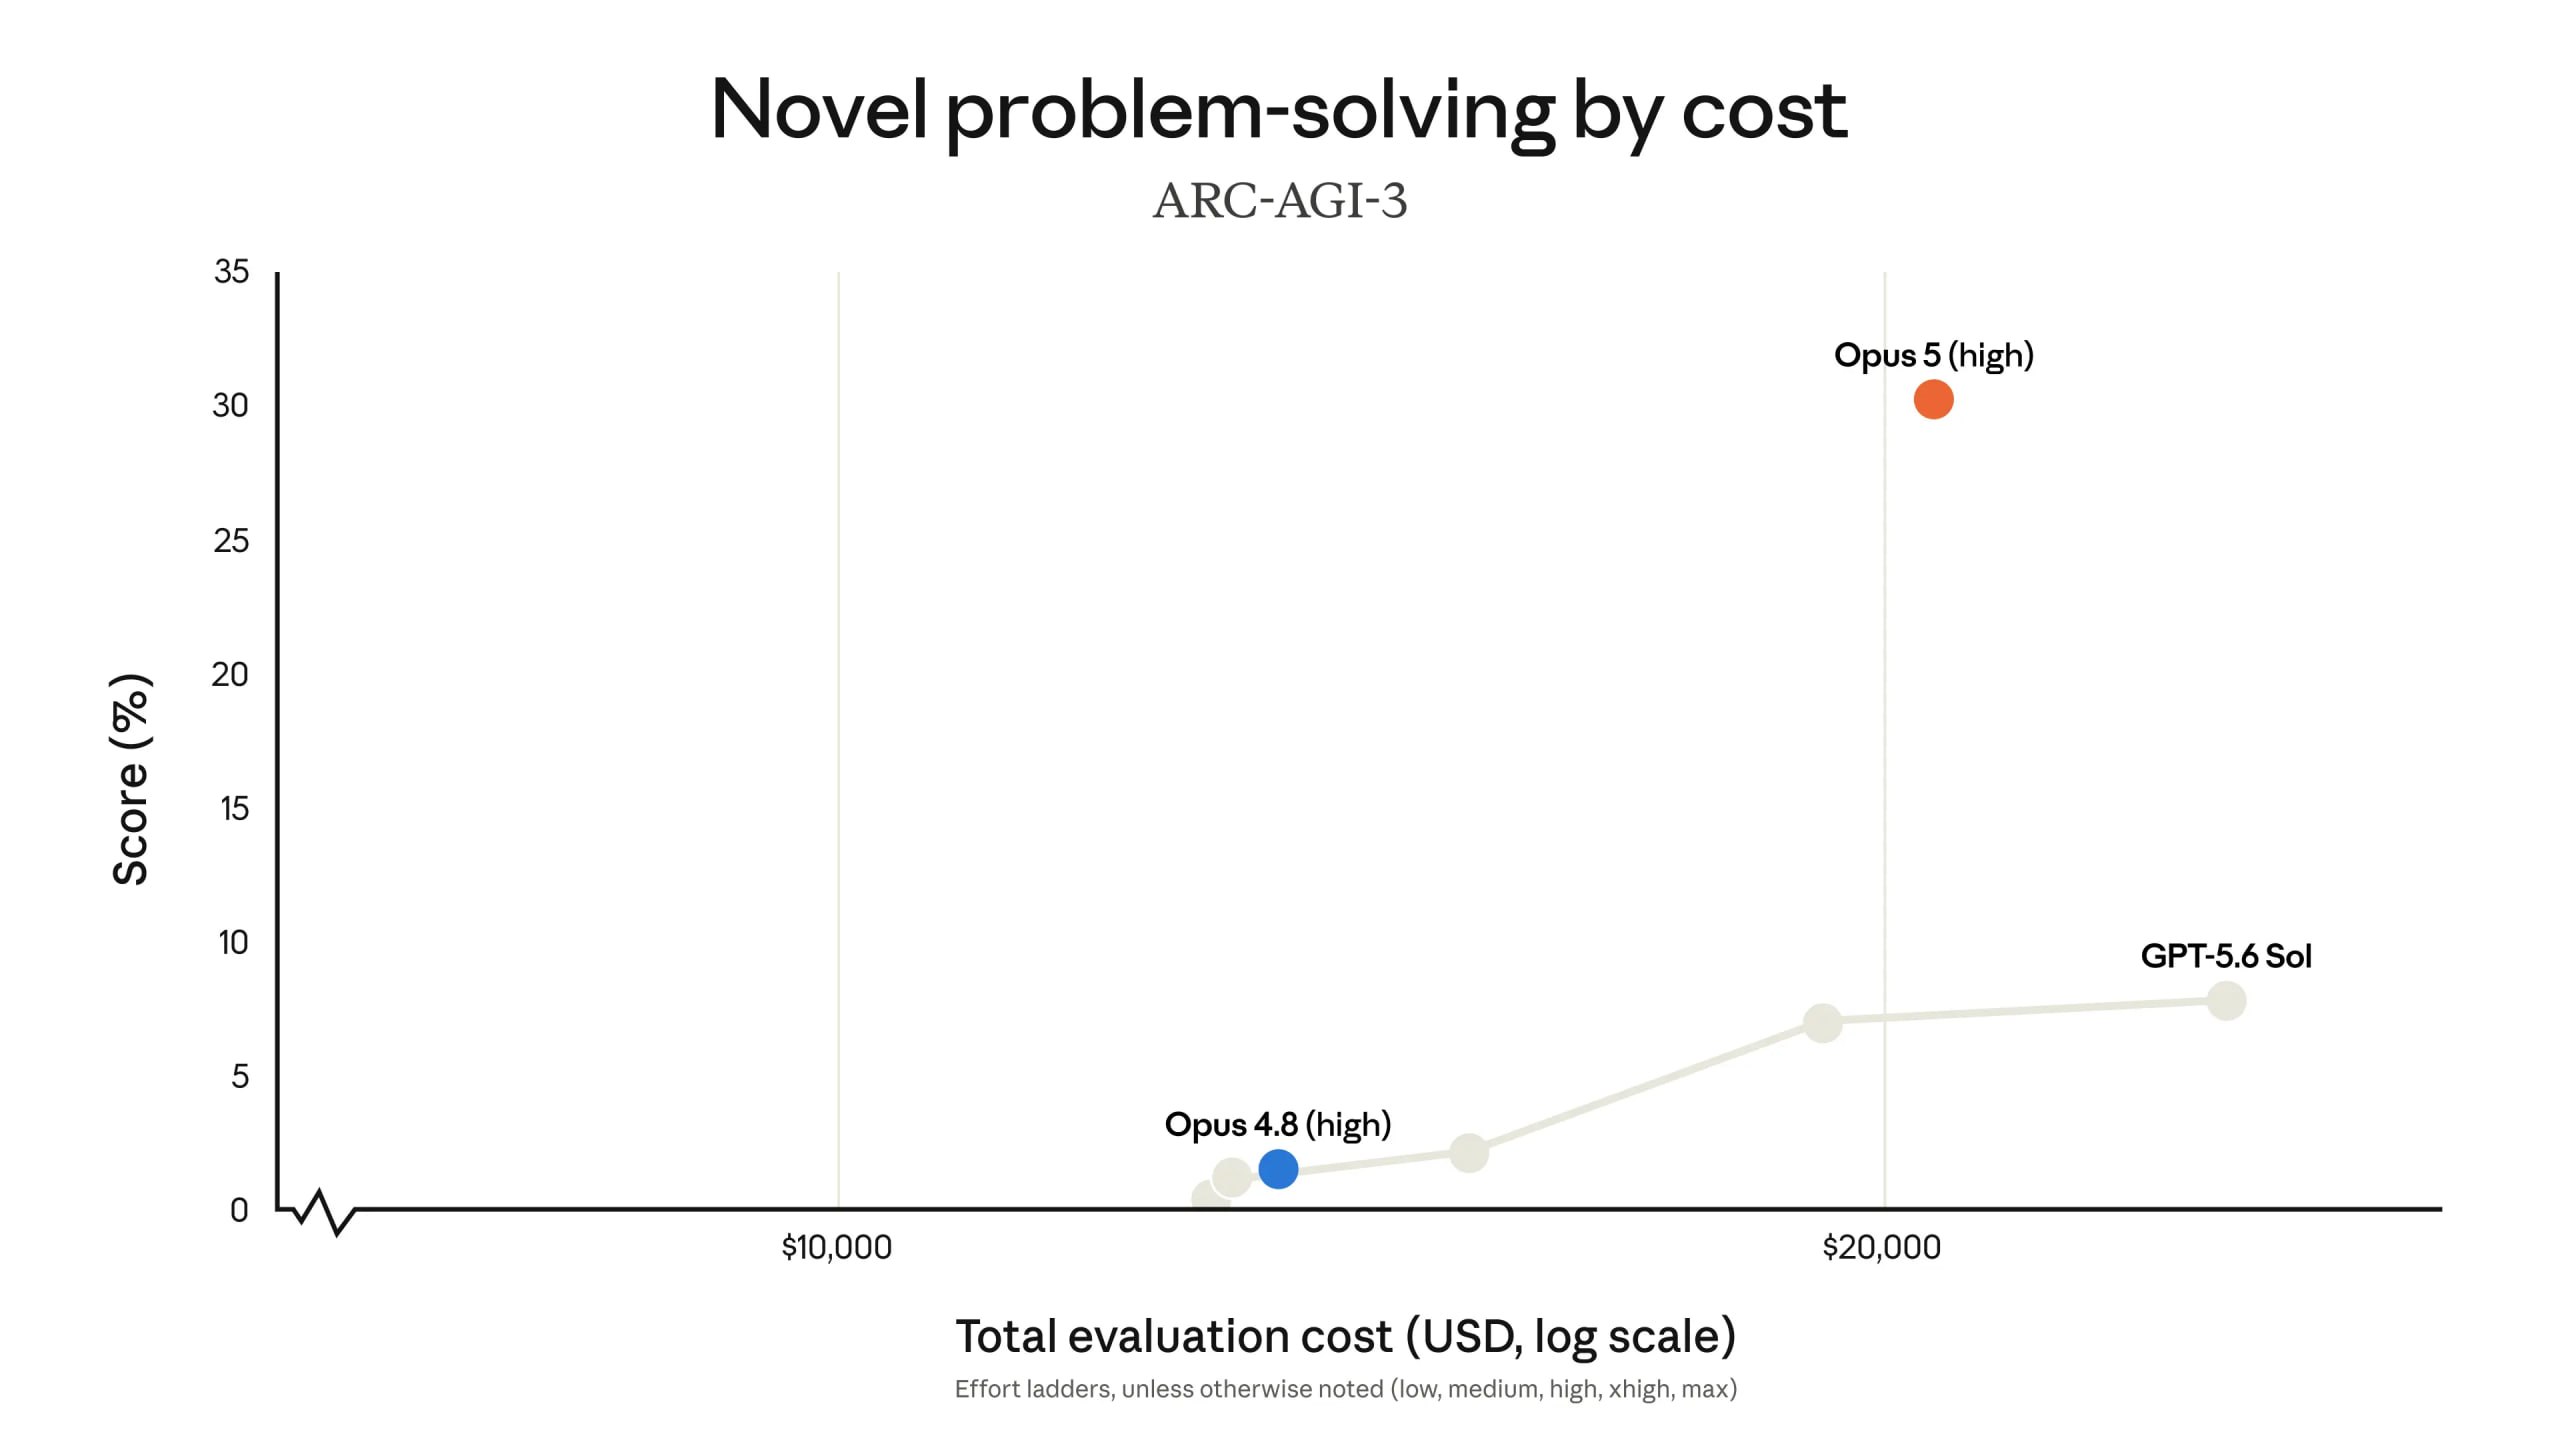
Graph titled "Novel problem-solving by cost" for benchmark ARC-AGI-3 showing Opus 5 (high) achieving 30% score at a total evaluation cost of around $20,000, significantly outperforming Opus 4.8 and GPT-5.6 Sol.
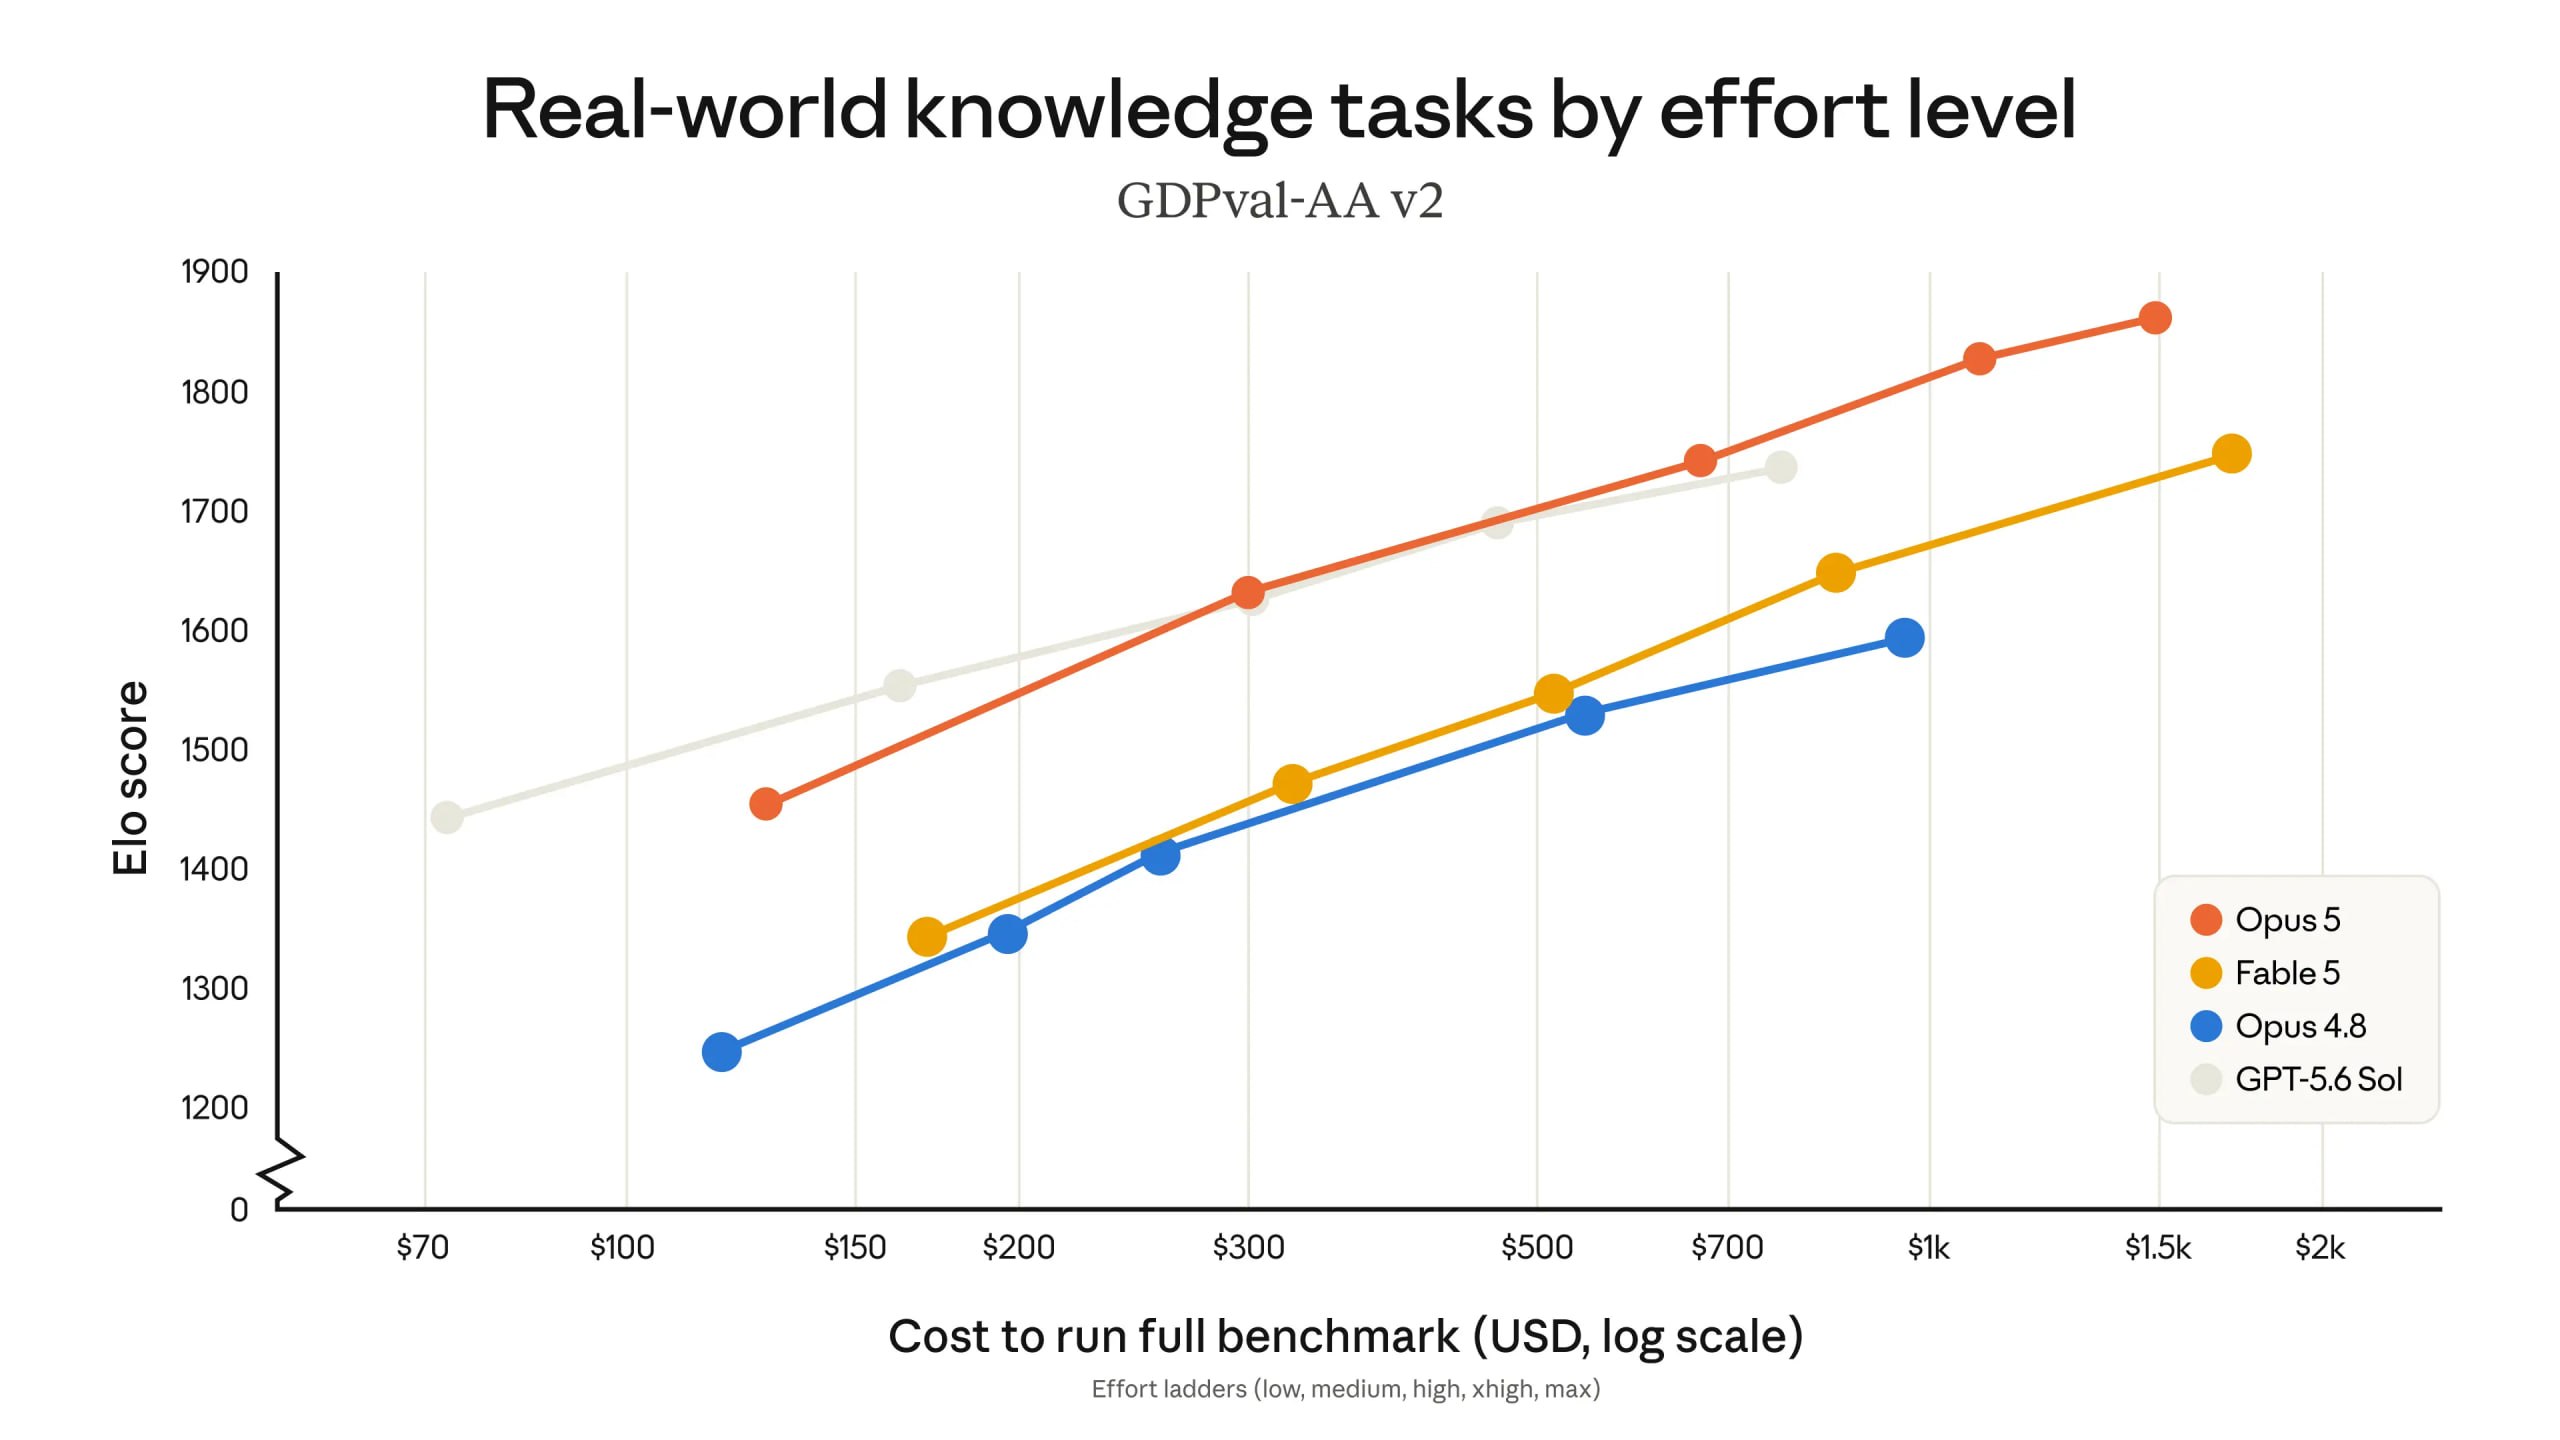
Graph titled "Real-world knowledge tasks by effort level" for benchmark GDPval-AA v2 showing Opus 5 (red line) achieving the highest Elo score at various costs to run the full benchmark, outperforming Fable 5, Opus 4.8, and GPT-5.6 Sol.
Graph titled "Agentic computer use performance by effort level" for benchmark OSWorld 2.0 showing Opus 5 (red line) reaching the highest score (around 70%) at a cost of about $20 per task, outperforming Fable 5, Opus 4.8, and GPT-5.6 Sol.
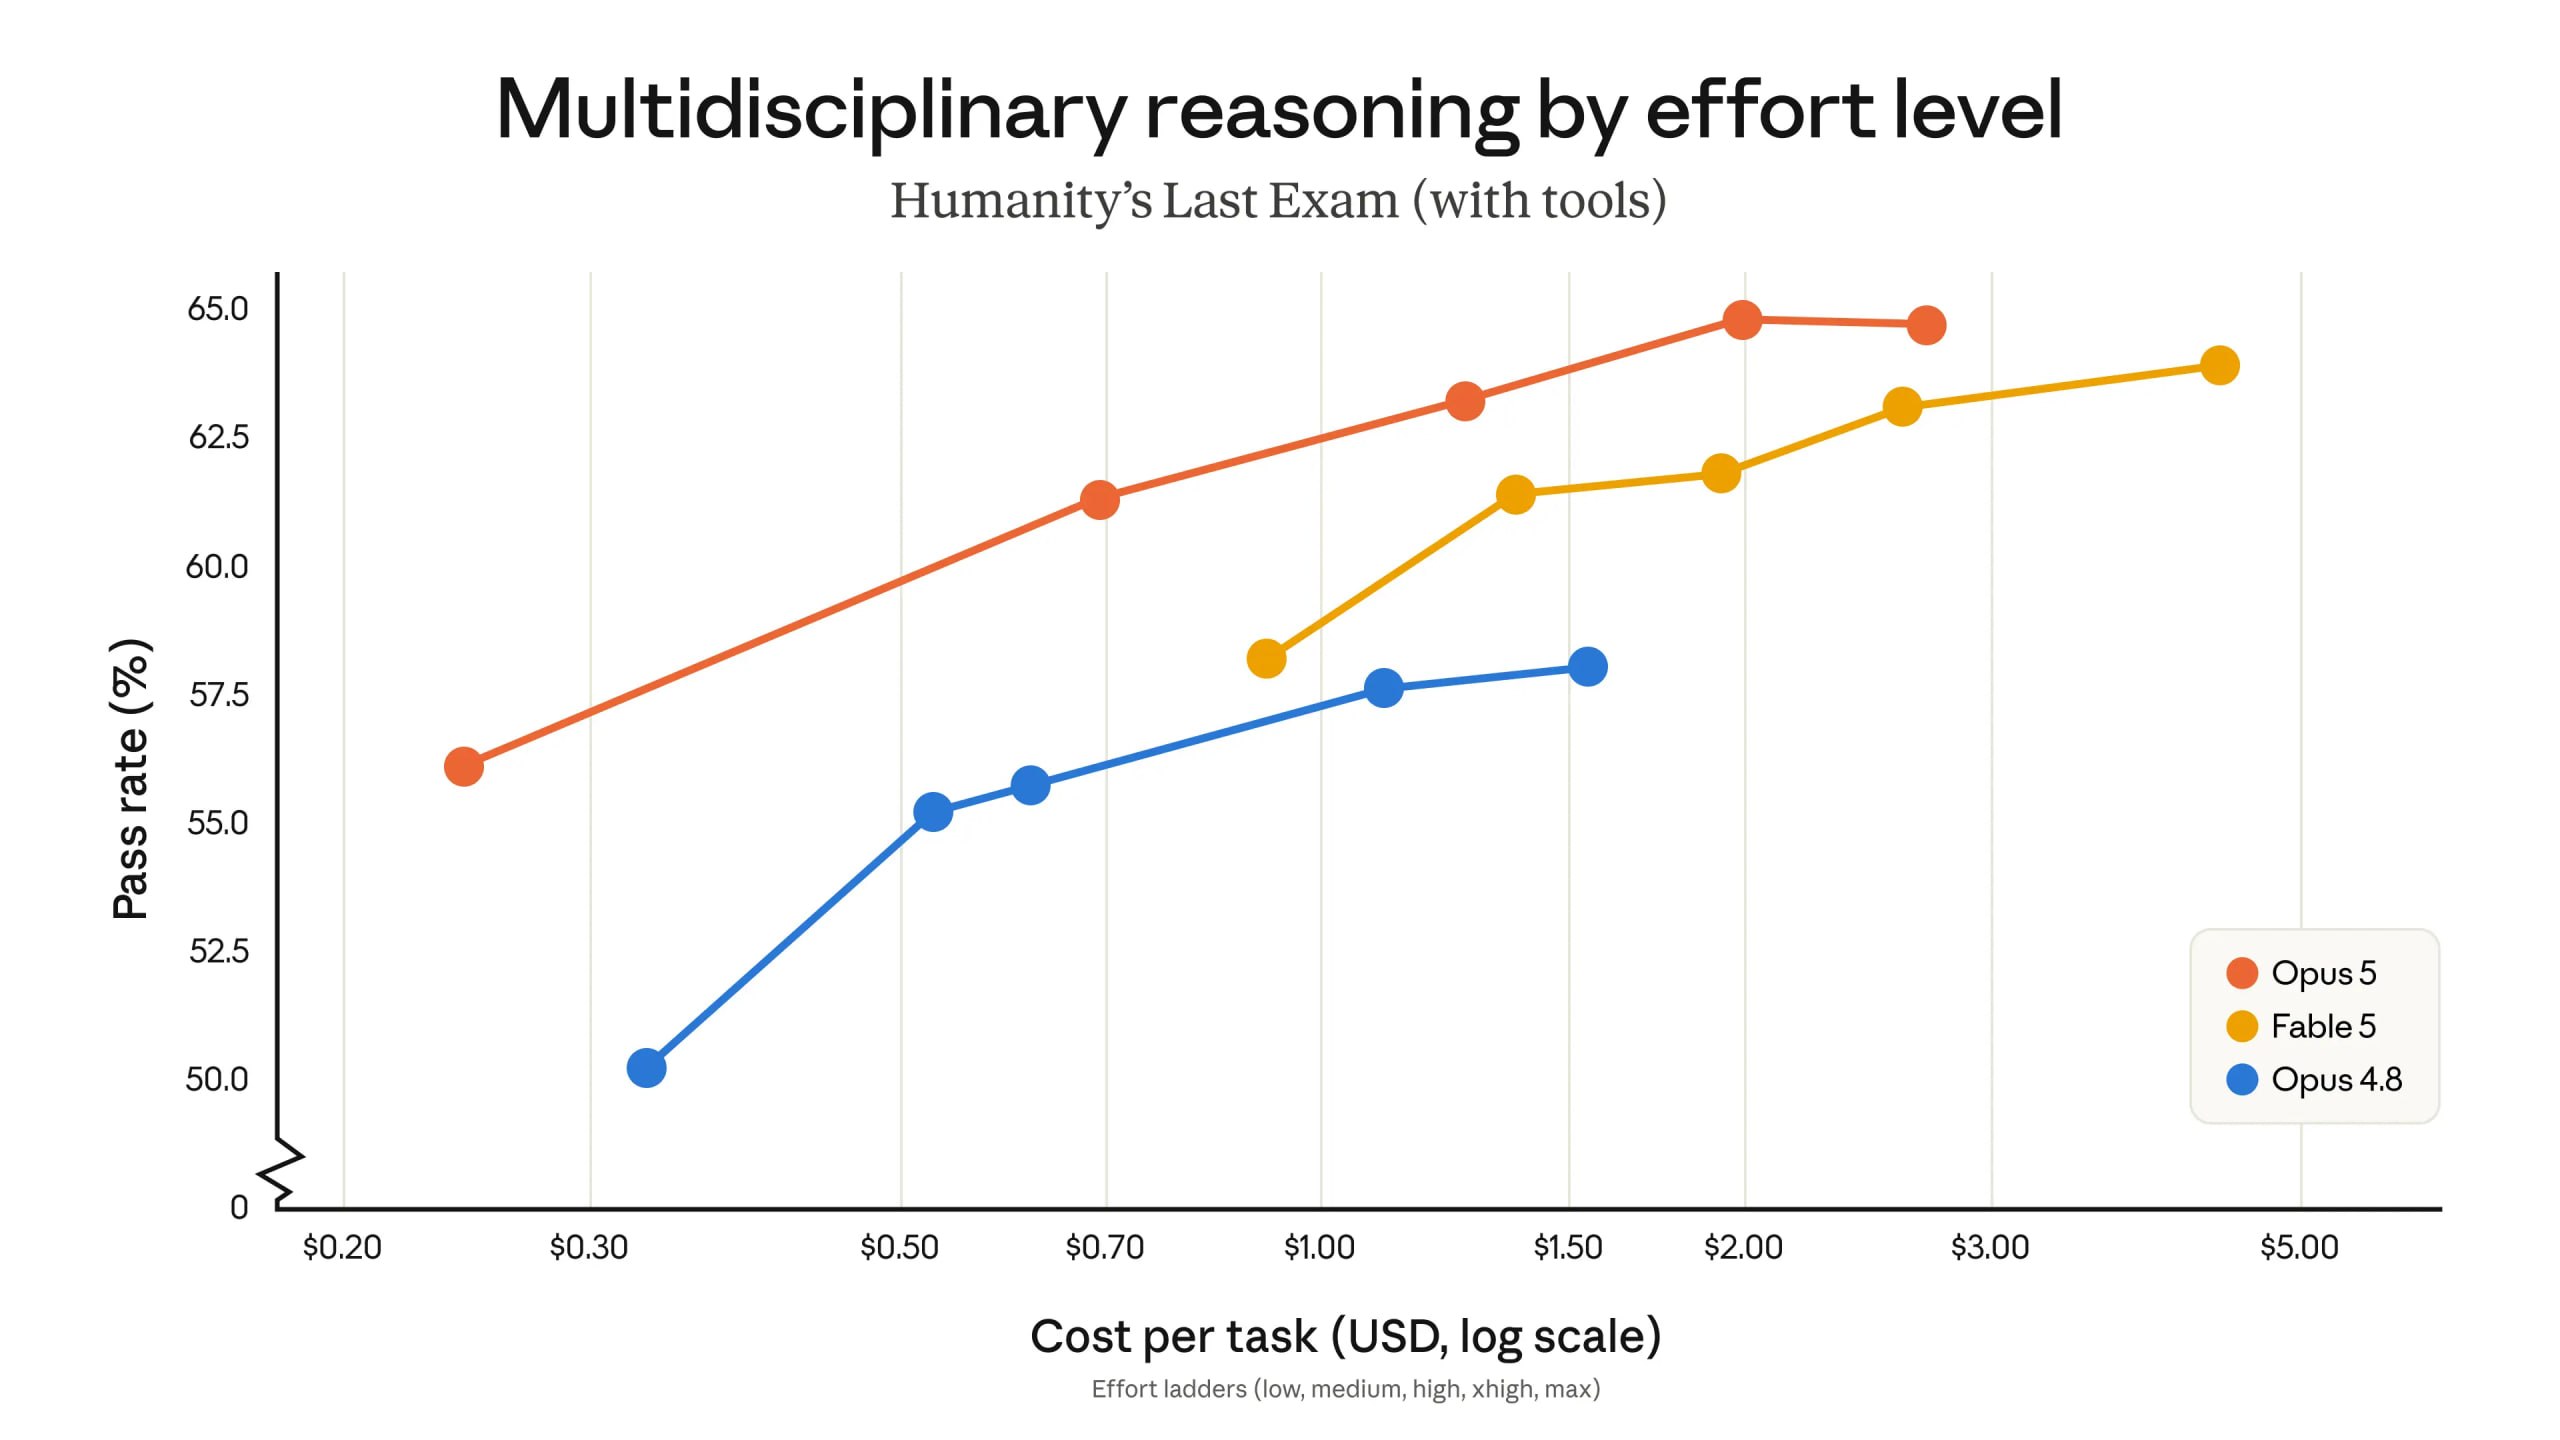
Graph titled "Multidisciplinary reasoning by effort level" for benchmark Humanity's Last Exam (with tools) showing Opus 5 (red line) achieving the highest pass rate (up to 65%) at task costs up to $3, outperforming Fable 5 and Opus 4.8.
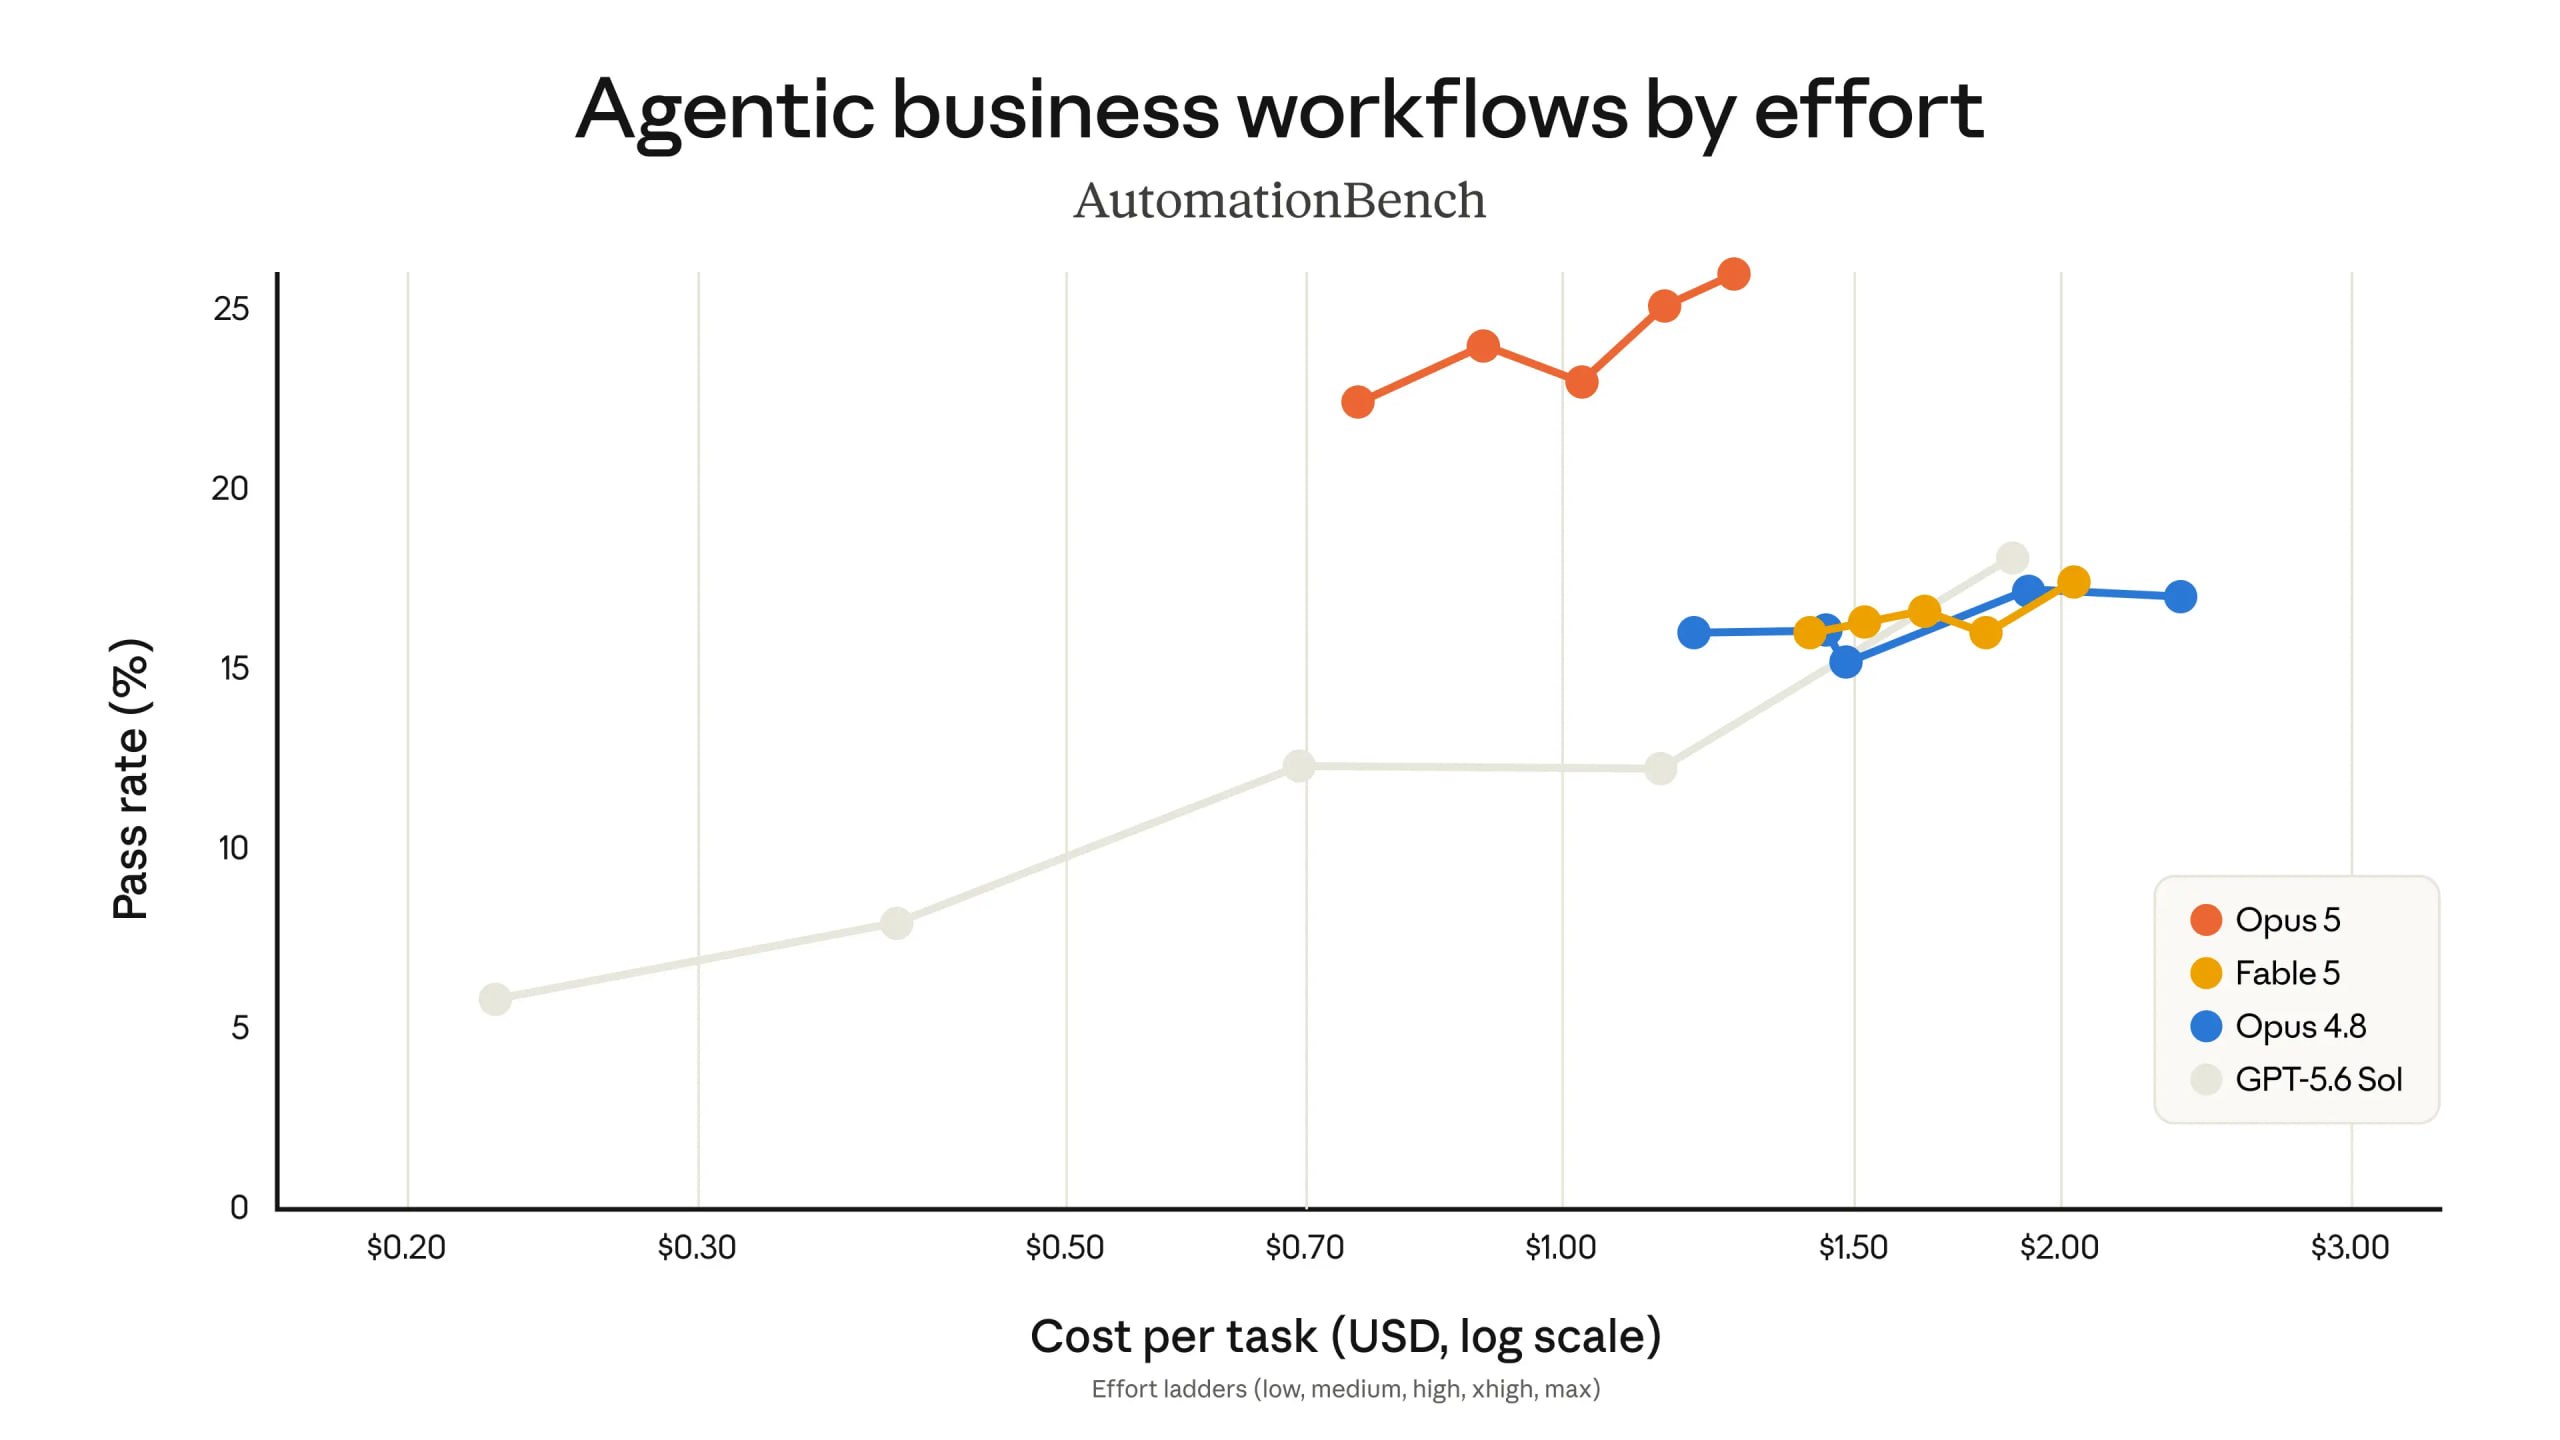
Graph titled "Agentic business workflows by effort" for benchmark AutomationBench showing Opus 5 (red line) reaching the highest pass rate (up to 25%) at a task cost of around $1.2, significantly outperforming other models.
Graph titled "Agentic search by effort level" for benchmark DeepSearchQA showing Opus 5 (red line) achieving the highest pass rate (up to 95%) at a task cost of around $3.5, outperforming Fable 5 and Opus 4.8.
ClaudeFable 5AnthropicClaude
Русская версияMarkdown

Analysis

Related posts